 DAKERA
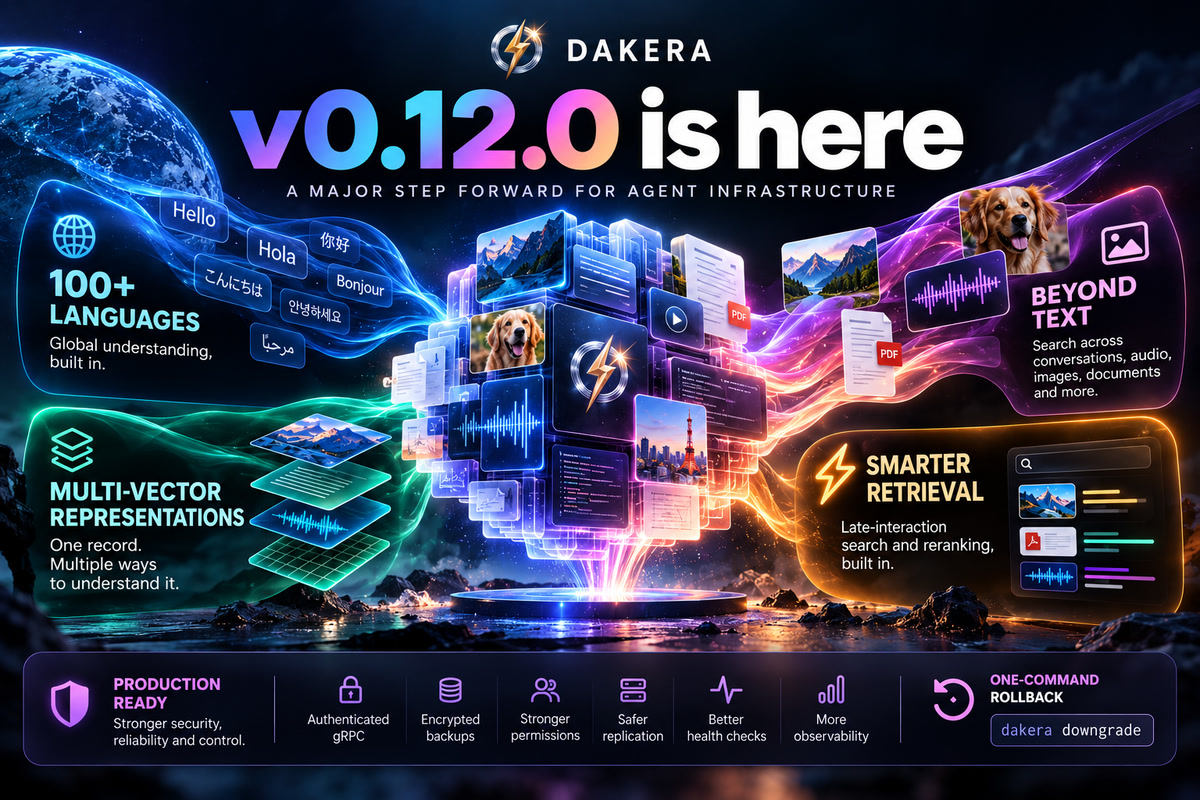
Today we’re releasing Dakera v0.12.0, the largest release in Dakera’s history and a milestone for self-hosted agent memory. Your agents can now remember in more than 100 languages, learn from documents, screenshots and voice notes, and recall faster on a fraction of the memory. All of it runs on your own hardware, on CPU, with nothing sent to anyone else’s model.
Agent memory has mostly meant English text. Real work doesn’t look like that. Support tickets arrive in German and Japanese. Finance teams live in scanned statements and tables. Field teams talk into their phones. v0.12.0 is built for that world, and built to keep the most sensitive data your agents hold exactly where it belongs: with you.
An agent’s memory holds the most sensitive data it touches. It should live on your hardware, in your users’ language, whatever form it arrives in.
Memory in your users’ languages
With bge-m3, memories in different languages share one vector space. A question asked in Japanese finds the answer your agent stored in English, and a German ticket lands next to the French one about the same outage. bge-m3 covers more than 100 languages, keeps the same 1024 dimensions as our English model, handles long inputs and runs on CPU.
We put it through a cross-lingual check before shipping: twelve facts stored in English, the same twelve questions asked in German, French, Spanish, Russian, Chinese and Japanese. bge-m3 put the right memory first for all 72.
Full-text search speaks the same languages: stemming and stop words per language, Chinese, Japanese and Korean indexing, dates understood in seven query languages, and a language setting on every request. See Multilingual search.
Memory from documents, screenshots and voice
Much of what an agent should remember never arrives as clean text. v0.12.0 lets it learn from what people actually send, and opens up a new class of agents:
The screenshot or scanned form a customer sent becomes searchable by what it shows.
Reports and statements are found by what is on the page, tables and layout included.
A voice note recorded on site becomes a memory, in whatever language it was spoken.
Manuals, slide decks and archives become a searchable archive, queried in plain language.
Document pages are embedded as images with colmodernvbert, a compact visual retrieval model built for CPU. On ViDoRe, the standard benchmark for visual document retrieval, it reaches nDCG@5 0.7705 on Shift Project and 0.643 on TabFQuAD.
Voice notes become memories through Whisper. The default, whisper-base, detects the spoken language among about 99 and records it on the memory.
Attachments live next to the memories that reference them, and they’re included in backups and replicated across a cluster like everything else. Each capability switches on with one setting. See Multimodal memory.
Precision when you need it
Some workloads need more than one vector per memory. Multi-vector records keep one indexed vector together with named extra representations, such as token or page-patch multivectors, stored at full or reduced precision and carried through every backend, snapshot, export and replication. See Records and multi-vector.
Late interaction scores memories token by token: switch to colbert-small and recall reranks with MaxSim. RaBitQ adds a compressed search mode for lower latency, and new rerank controls let you cap how many candidates the cross-encoder scores on each request. See Search and ranking.
Pick the models that fit
Every team’s data is different, so v0.12.0 gives you a tested set of models with a sensible default for each job. Switching is supported.
| Model | Role | Use it when |
|---|---|---|
| Text embeddings | ||
| bge-large default | English text, shipped inside the image | Your agents work in one language. |
| bge-m3 | 100+ languages in one space, long inputs | Your users write in more than one language. |
| colbert-small | Token-level late interaction | Fine-grained matching matters most. |
| Speech to text | ||
| whisper-base default | Multilingual, detects the spoken language | Most teams: good accuracy at modest cost. |
| whisper-small | Multilingual, highest accuracy | Quality matters more than CPU time. |
| whisper-tiny | Multilingual, lighter | Small machines with mixed languages. |
| whisper-tiny.en whisper-base.en | English, lightest | Your audio is in English. |
| Document pages | ||
| colmodernvbert | Embeds the page image, tables and layout included | Your memories start as scans, slides or screenshots. |
Every model runs on CPU inside the engine. bge-large and the reranker ship in the Docker image; the others download once on first use, or ahead of time for air-gapped installs.
Faster and leaner
We rebuilt how Dakera runs its models: one memory-mapped copy of each, lean single-threaded workers, and memory reserved before heavy work begins. The result: millisecond vector search, reranking about twice as fast on the same CPU, and a fraction of the memory.
All figures CPU-only. Vector search and index memory: HNSW on BEIR Quora, 50,000 vectors of 1024 dimensions, recall@10 0.998 (index memory 4.81 → 2.76 KB per vector). Reranking and memory after reranking: 4 vCPU / 8 GiB container with bge-reranker-v2-m3, compared with v0.11.108 on the same machine; flat across 1 to 32 results. Multimodal stack: anonymous memory with every model loaded. Ingest: the same workload on v0.11.108 and v0.12.0. The Docker image is about 0.8 GB, ready in about 4.4 s with zero downloads, so it runs air-gapped. Details on the performance page.
Private by design, secure by default
Dakera runs where your data already lives. Recall never calls an LLM, and nothing leaves your infrastructure unless you choose it: if you want LLM-powered entity extraction, the /v1/extract endpoint can use a provider you configure, and it’s off until you do.
v0.12.0 also raises the security bar across the engine:
- gRPC requires an API key and is rate limited and audited like REST;
- traffic between cluster nodes is authenticated with a shared secret;
- encrypted values are bound to their record, with per-namespace key rotation;
- namespace-scoped keys stay within their namespaces, and backups require a global admin key.
See Security.
Upgrade in place, roll back in one command
An existing v0.11.108 deployment upgrades in place, and every new capability stays off until you switch it on. Stored memories are refreshed in the background while recall keeps serving.
- Give gRPC clients an API key when authentication is on.
- Use a global key for node-wide admin tooling, and a
super_adminkey for backups. - Ranking now follows the query more closely; re-check any absolute score thresholds.
- Point readiness probes at
/health/ready, and rundakera --check-configfirst.
The full checklist is in the upgrade guide.
Stop v0.12.0, run the downgrade once with the same environment and volumes, then start v0.11.108:
docker run --rm <your env and volumes> \
  ghcr.io/dakera-ai/dakera:0.12.0 downgrade
It checks before it changes anything. See Rolling back to v0.11.
What’s next
v0.12.0 is a foundation we’re excited to build on. More models are on the way, for speech and beyond, along with more integrations with the frameworks you already use. Updated clients that cover everything in this release are available today: the Python, TypeScript, Go and Rust SDKs, the dk CLI and the MCP server.
Thank you to everyone running Dakera in production. Your agents are about to remember a lot more.
Get started
docker run -d --name dakera -p 3000:3000 \
  -e DAKERA_ROOT_API_KEY=my-dev-key \
  -e DAKERA_STORAGE=filesystem \
  -v dakera-data:/data \
  ghcr.io/dakera-ai/dakera:0.12.0
Run v0.12.0 on your own hardware
A first memory in a few minutes, and the full release in the docs.